Long interactions with AI assistants often lead to a decline in response quality. This is not a failure of the underlying model, but rather a structural consequence of how LLM's handle memory. As a conversation progresses, the context window accumulates tokens from user inputs, system instructions, tool outputs, and historical messages. Managing this accumulation is essential for maintaining high-quality, cost-effective outputs. This post describes what context management is, why context engineering is important and how you can keep a clean context with Open Assistant, a versatile open-source AI assistant.
The Science of Context Rot: Why LLM Performance Degrades
Large language models process information within a finite context window, but a larger window is not always better. Research from Anthropic shows that as the number of tokens in a context window increases, the model's ability to accurately recall information decreases. This phenomenon, known as "context rot," emerges across all models regardless of their architecture.
Every token introduced into the system depletes a finite "attention budget." Because transformer architectures analyze pairwise relationships between all tokens, scaling the context length increases computational overhead quadratically. Context must therefore be treated as a finite resource with diminishing marginal returns.
Furthermore, models do not treat all parts of a prompt equally. According to research highlighted by Comet and Redis, large language models are highly proficient at utilizing information located at the beginning or the end of a prompt.
However, performance degrades significantly when the relevant information sits in the middle of a long context. This "lost in the middle" effect means that long, multi-topic threads inevitably lead to missed details and lower-quality reasoning.
Overloading the context window also carries operational penalties. As detailed by 16x Engineer, filling context windows carelessly increases latency and drives up API costs. Additionally, as noted by Redis, context overflow often happens before hitting hard token limits. Some systems handle this through silent truncation, dropping historical data without alerting the user, while latency rises steadily as prompts grow longer.
The Open Assistant Solution: The /clear Command
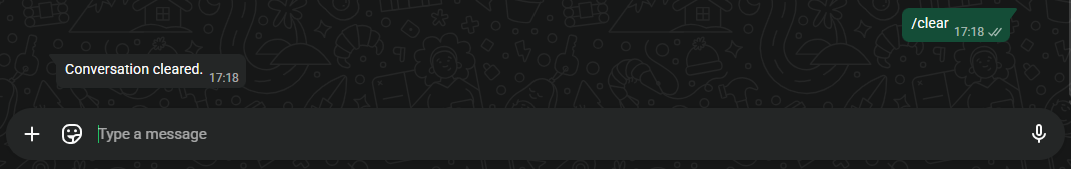
To prevent these performance bottlenecks, Open Assistant -- which can serve as a robust self-hosted AI assistant -- offers a straightforward mechanism to manage active memory. The /clear command, documented in the Open Assistant Commands Guide, allows users to instantly reset their active conversation thread. When executed, the assistant returns a simple confirmation: "Conversation cleared."
Under the hood, the /clear command generates a brand-new conversation with a fresh ID, routing all subsequent messages to this clean environment. This action resets the active context window, ensuring the model is not weighed down by previous tokens.
Crucially, clearing the conversation does not mean losing your data. Built to function as a highly private AI assistant, Open Assistant maintains a persistent memory architecture. The previous thread remains fully intact, searchable, and archived. Through the assistant's memory_recall tool and conversation search capabilities, the AI system can still access past interactions when they are genuinely relevant to the active task. The /clear command simply ensures that irrelevant historical noise does not clutter the active reasoning space.
When to Clear Your Context
To maintain peak efficiency, users should adopt a "one thread, one topic" rule of thumb to keep their self-hosted AI agent operating with maximum focus. When a specific task is complete, the context should be cleared before moving to the next. Mixed-topic threads confuse the model, making responses less focused and unnecessarily expensive.
Key indicators that it is time to use the /clear command include:
- Switching topics: Moving from code debugging to writing an email, or shifting between unrelated projects.
- Degraded sharpness: Observing a lag in response generation or noticing that the assistant's answers feel less precise.
- Outdated references: Noting that the assistant is referencing details from earlier in the chat that are no longer relevant to the current objective.
By proactively clearing the context, users minimize token usage, which directly reduces operational latency and prevents unnecessary API expenditures.
Get Started
Clean context is the foundation of precise AI performance. By utilizing the /clear command, users can bypass context rot and keep the assistant operating at maximum speed and accuracy.
To learn more about the system's architecture and capabilities, visit the Open Assistant website.